Fix one recurring problem in your software
A service stops again and again. Your customers find failures before your team does. One part of the code makes each change slow. In each engagement, we fix one of these problems. We agree the scope before you pay, and we test the change in your stack. After the first fix, you can stop or continue.
A problem that your team does not have time to fix
You do not need to know the cause. Tell us the symptom and give a recent example. We then tell you if one change can fix it.
The same service stops again and again, and a person must restart it manually.
We find out about a failure when a customer tells us.
When a failure occurs, our logs do not show what happened.
One part of the code makes each change slow and risky.
We fix one recurring problem in your stack and prove that the fix works
We agree the scope before you pay. If the work is larger, we write a separate proposal. We do not make large work smaller to fit the price.
Point of Failure Solution
$3,00010 business days after you give us accessOne change to one service or component. We make the change, test it and give it to your team.
- The change in your repository. We deploy it after you approve it.
- Automated tests and a record of the acceptance tests, with all known limits
- An architecture note, an operating guide and rollback instructions
- A one-hour walkthrough with your maintainer. For 14 days, we correct defects in our work.
- One recurring problem in one service or component, agreed before you pay
- One repository, with its production and staging environments
- Acceptance tests that your reviewer approves before we start
- Changes to production only with your approval and a rollback procedure
- You pay 50% when you book and 50% when you accept the work
- The 10 days start when we have access and all prerequisites
- Any defects in our work are corrected in the following 14 days
- Incident response and on-call support
- Security audits and compliance audits
- Cloud and tool costs from third parties. We tell you about them before you buy.
Three types of fixes
These examples show the size of the work. They are not client results. We do one of these changes, or a different change of the same size.
A service that stops again and again
- Move the service to a redundant managed runtime, with no change to its interface
- Show that health checks, deployment and rollback work
- Test recovery from an agreed failure
Failures that your customers see first
- Add structured logs, a small dashboard and alerts
- Cause a controlled failure, then trace it and send an alert
- Write a runbook for triage and ownership
One component that makes each change slow
- Move the component into a package with a documented interface
- Add contract tests that keep the current behavior
- Connect your app to the package, so that your maintainer can change it
Our team has built and operated similar systems
Our team delivered lead pipelines, partner integrations and national secure systems, at Plisken Corp. and in previous roles.
Sales pipeline and CRM
- A custom pipeline with its own CRM, tracking and dashboard
- Custom cohorts to compare campaigns and lead sources
Partner integrations
- Integrations with fulfillment partners and third-party service partners
- Standard APIs
National secure systems
- Access control for records across a national network
We check the fit, make the change and give it to your team
Scope
First, we do a short fit check. Then we write the scope: the symptom, the change, the acceptance tests and the rollback procedure. If a smaller fix or a larger project is better for you, we tell you.
Build
We make the change in your stack. We test it against the agreed criteria and send you the evidence during the work. No change goes to production without your approval.
Hand over
We deploy the change after you approve it. Then we show your team how it works and give them an operating guide. For 14 days, we correct defects in our work.
A senior engineer does the work
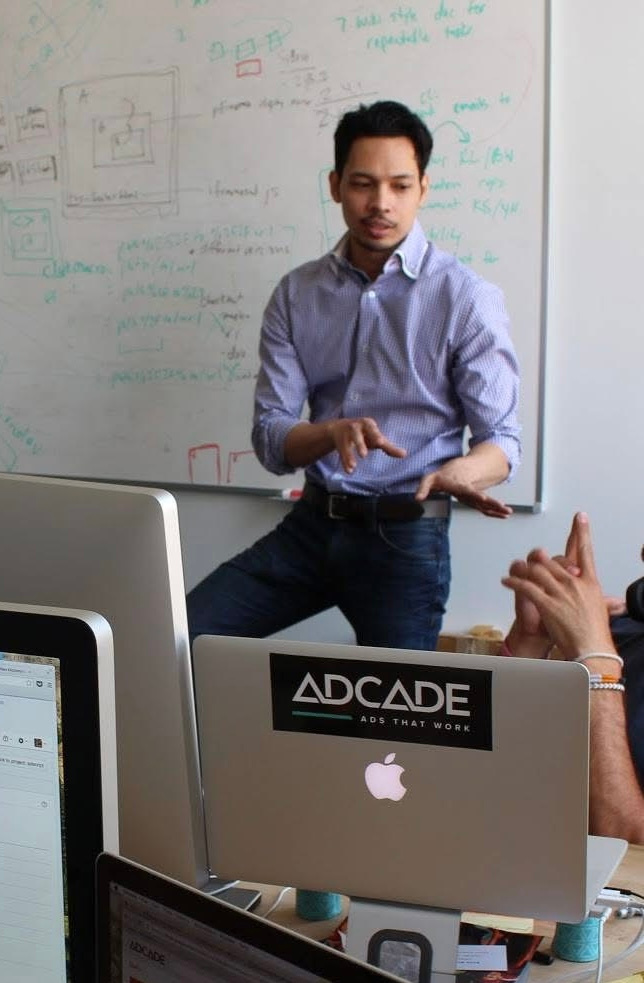
When the same problem occurs again and again, teams can work around it for months. I help you choose one change that is worth the cost. I make it in your stack, prove that it works and teach your team to operate it.
Each engagement has a written contract, a senior lead and a documented handover
Tell us about the problem
A senior principal reads each inquiry. We reply by email and tell you if one fix is applicable. If a smaller fix or a larger project is better, we tell you. Do not send passwords or code. This form does not book or buy a service.
Discuss a problem to fix
FAQ
- No. Tell us the symptom and give a recent example. A short fit check shows if one change can fix the problem. If it cannot, we tell you before you pay.
- No. The price includes one limited change in one service or component, in a stack that we know well. If a simpler fix is sufficient, we tell you. If the work is larger, we write a separate proposal.
- For the fit check, a description and redacted excerpts are usually sufficient. For the work, you give us temporary accounts for the agreed repository and environments. You remove them when we finish. Do not send credentials in the form or by email.
- Only with your approval. The change must first pass in staging, and we must have a tested rollback procedure. We agree on each maintenance window before it starts.
- Your team owns and operates the change. For 14 days, we correct defects in the work that we delivered. If you want more work, we quote it separately. There is no retainer.
- No. We fix one technical problem. If we find a problem that needs a specialist, we tell you.
- A senior principal leads each engagement. Backup engineers help when the work needs them.
- We work remotely with clients in the US and the EU.
Start with one problem
In a short call, we discuss what fails and if one change can fix it.
- If one fix is applicable to your problem
- What the change and its acceptance tests are
- If a smaller fix or a larger project is better